A study of sequence weighting at scale
TL;DR: We study the scaling laws of data weighting across in-house and open-weight LMs, finding non-monotonic behavior across scales. We vary the weight assigned to...
TL;DR: We study the scaling laws of data weighting across in-house and open-weight LMs, finding non-monotonic behavior across scales. We vary the weight assigned to...
Attention is a computational primitive at the core of modern language models, allowing internal representations to reference and influence each other. It’s how these models...

Jane Street is running a Kaggle contest based on a real problem with real financial data. If you like ML projects, or think you might,...
Updates and a New Run

If you haven’t heard of it, Depth First Learning is a wonderful resource for learning about machine learning.
At Jane Street, over the last few years, we’ve been increasingly exploring machine learning to improve our models. Many of us are fascinated by the...
This blog post is about an interesting detail about machine learning that I came across as a researcher at Jane Street - that of the...
At Jane Street, we often work with data that has a very low signal-to-noise ratio, but fortunately we also have a lot of data. Where...
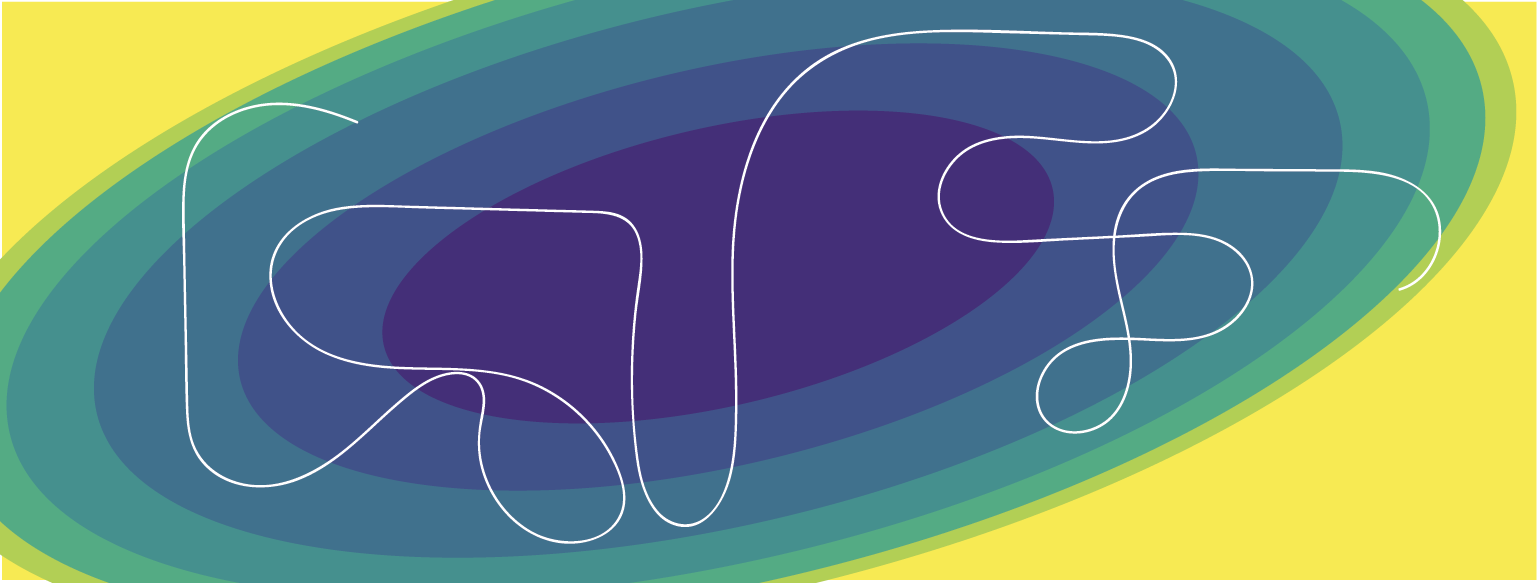
This post is aimed at readers who are already familiar with stochastic gradient descent (SGD) and terms like “batch size”. For an introduction to these...
Trading is a competitive business. You need great people and great technology, of course, but also trading strategies that make money. Where do those strategies...